 text-to-image
Seedream
bytedance/seedream/v5/flash/text-to-imageSeedream 5.0 Flash is a fast image generation and editing model, built for workflows where speed and budget matter.
Browse the public fal model directory. Models become callable through Kaista Cloud only after supply, pricing, and compatibility review.
text-to-imagebytedance/seedream/v5/flash/text-to-imageSeedream 5.0 Flash is a fast image generation and editing model, built for workflows where speed and budget matter.
 text-to-image
fal-ai/krea-2/turboGenerate high-fidelity images from text in seconds with Krea 2 Turbo, the speed-optimized open-source version of Krea 2, preserving its aesthetic range for rapid ideation.
 image-to-video
bytedance/seedance-2.0/mini/image-to-videoSeedance 2.0 Mini is a faster version of Seedance 2.0 that brings great performance and high generation speed at a lower cost.
 image-to-image
xai/grok-imagine-image/quality/editGrok Imagine Pro is an advanced AI model from xAI that creates high-quality visuals from text prompts and allows you to edit or analyze existing images.
 text-to-audio
sonilo/v1.1/text-to-musicGenerates licensed, commercial-use-safe music from a single text prompt, with full control over style, mood, instrumentation, and exact duration.
 image-to-image
fal-ai/flux-pro/kontext/max/multiExperimental version of FLUX.1 Kontext [max] with multi image handling capabilities
 image-to-video
fal-ai/wan/v2.7/image-to-videoWan 2.7 is the latest generation AI video model, delivering enhanced motion smoothness, superior scene fidelity, and greater visual coherence.
 text-to-image
fal-ai/qwen-imageQwen-Image is an image generation foundation model in the Qwen series that achieves significant advances in complex text rendering and precise image editing.
 text-to-audio
 text-to-video
bytedance/seedance-2.0/fast/text-to-videoByteDance's most advanced text-to-video model, fast tier. Lower latency and cost with cinematic output, native audio, multi-shot editing, and director-level camera control.
 text-to-image
alibaba/qwen-image-3/text-to-imageGenerates images from a text prompt at resolutions up to 2048×2048, with automatic prompt rewriting and prompt-guided resolution selection, building on Qwen's strength in complex text rendering and precise prompt adherence
 image-to-video
blackforestlabs/flux-3/image-to-videoFLUX 3 is Black Forest Labs' frontier video model. This endpoint animates a single still image into video, extending one frame into coherent, natural motion.
 image-to-image
bria/fibo-2/editFibo 2.0 Edit makes targeted, instruction-based edits from up to four images. Background swaps, product restaging, keeping the product true to the original. Trained only on licensed data, with clear commercial rights.
 video-to-video
fal-ai/birefnet/v2/videoVideo background removal version of bilateral reference framework (BiRefNet) for high-resolution dichotomous image segmentation (DIS)
 image-to-video
google/gemini-omni-flash/image-to-videoAnimates a still image into video with audio. Extends a single frame into coherent motion, grounded in Gemini's physical understanding of how scenes and subjects behave.
 text-to-image
fal-ai/flux-2-maxFLUX.2 [max] delivers state-of-the-art image generation and advanced image editing with exceptional realism, precision, and consistency.
 video-to-video
fal-ai/kling-video/o1/video-to-video/editEdit an existing video using natural-language instructions, transforming subjects, settings, and style while retaining the original motion structure.
 text-to-audio
 image-to-video
bytedance/seedance-2.0/mini/reference-to-videoSeedance 2.0 Mini is a faster version of Seedance 2.0 that brings great performance and high generation speed at a lower cost.
 video-to-video
veed/lipsyncGenerate realistic lipsync from any audio using VEED's model.
 image-to-image
fal-ai/evf-samEVF-SAM2 combines natural language understanding with advanced segmentation capabilities, allowing you to precisely mask image regions using intuitive positive and negative text prompts.
 text-to-audio
fal-ai/kokoro/american-englishKokoro is a lightweight text-to-speech model that delivers comparable quality to larger models while being significantly faster and more cost-efficient.
 text-to-image
fal-ai/recraft/v4.1/text-to-imageRecraft V4.1 builds on the design-first foundation of V4 with sharper prompt control and cleaner composition. Tuned for brand systems and editorial work, it delivers production-ready raster images that hold up next to a designer's hand.
 speech-to-speech
resemble-ai/chatterboxhd/speech-to-speechTransform voices using Resemble AI's Chatterbox. Convert audio to new voices or your own samples, with expressive results and built-in perceptual watermarking.
 audio-to-audio
fal-ai/elevenlabs/voice-changerChange the voices in your audios with voices in ElevenLabs!
 image-to-video
fal-ai/kling-video/v3/turbo/pro/image-to-videoGenerate high quality 1080p videos from images using Kling's Turbo 3.0 model, with improved lipsync and multishot generation capabilities.
 video-to-video
fal-ai/sam-3/videoSAM 3 is a unified foundation model for promptable segmentation in images and videos. It can detect, segment, and track objects using text or visual prompts such as points, boxes, and masks.
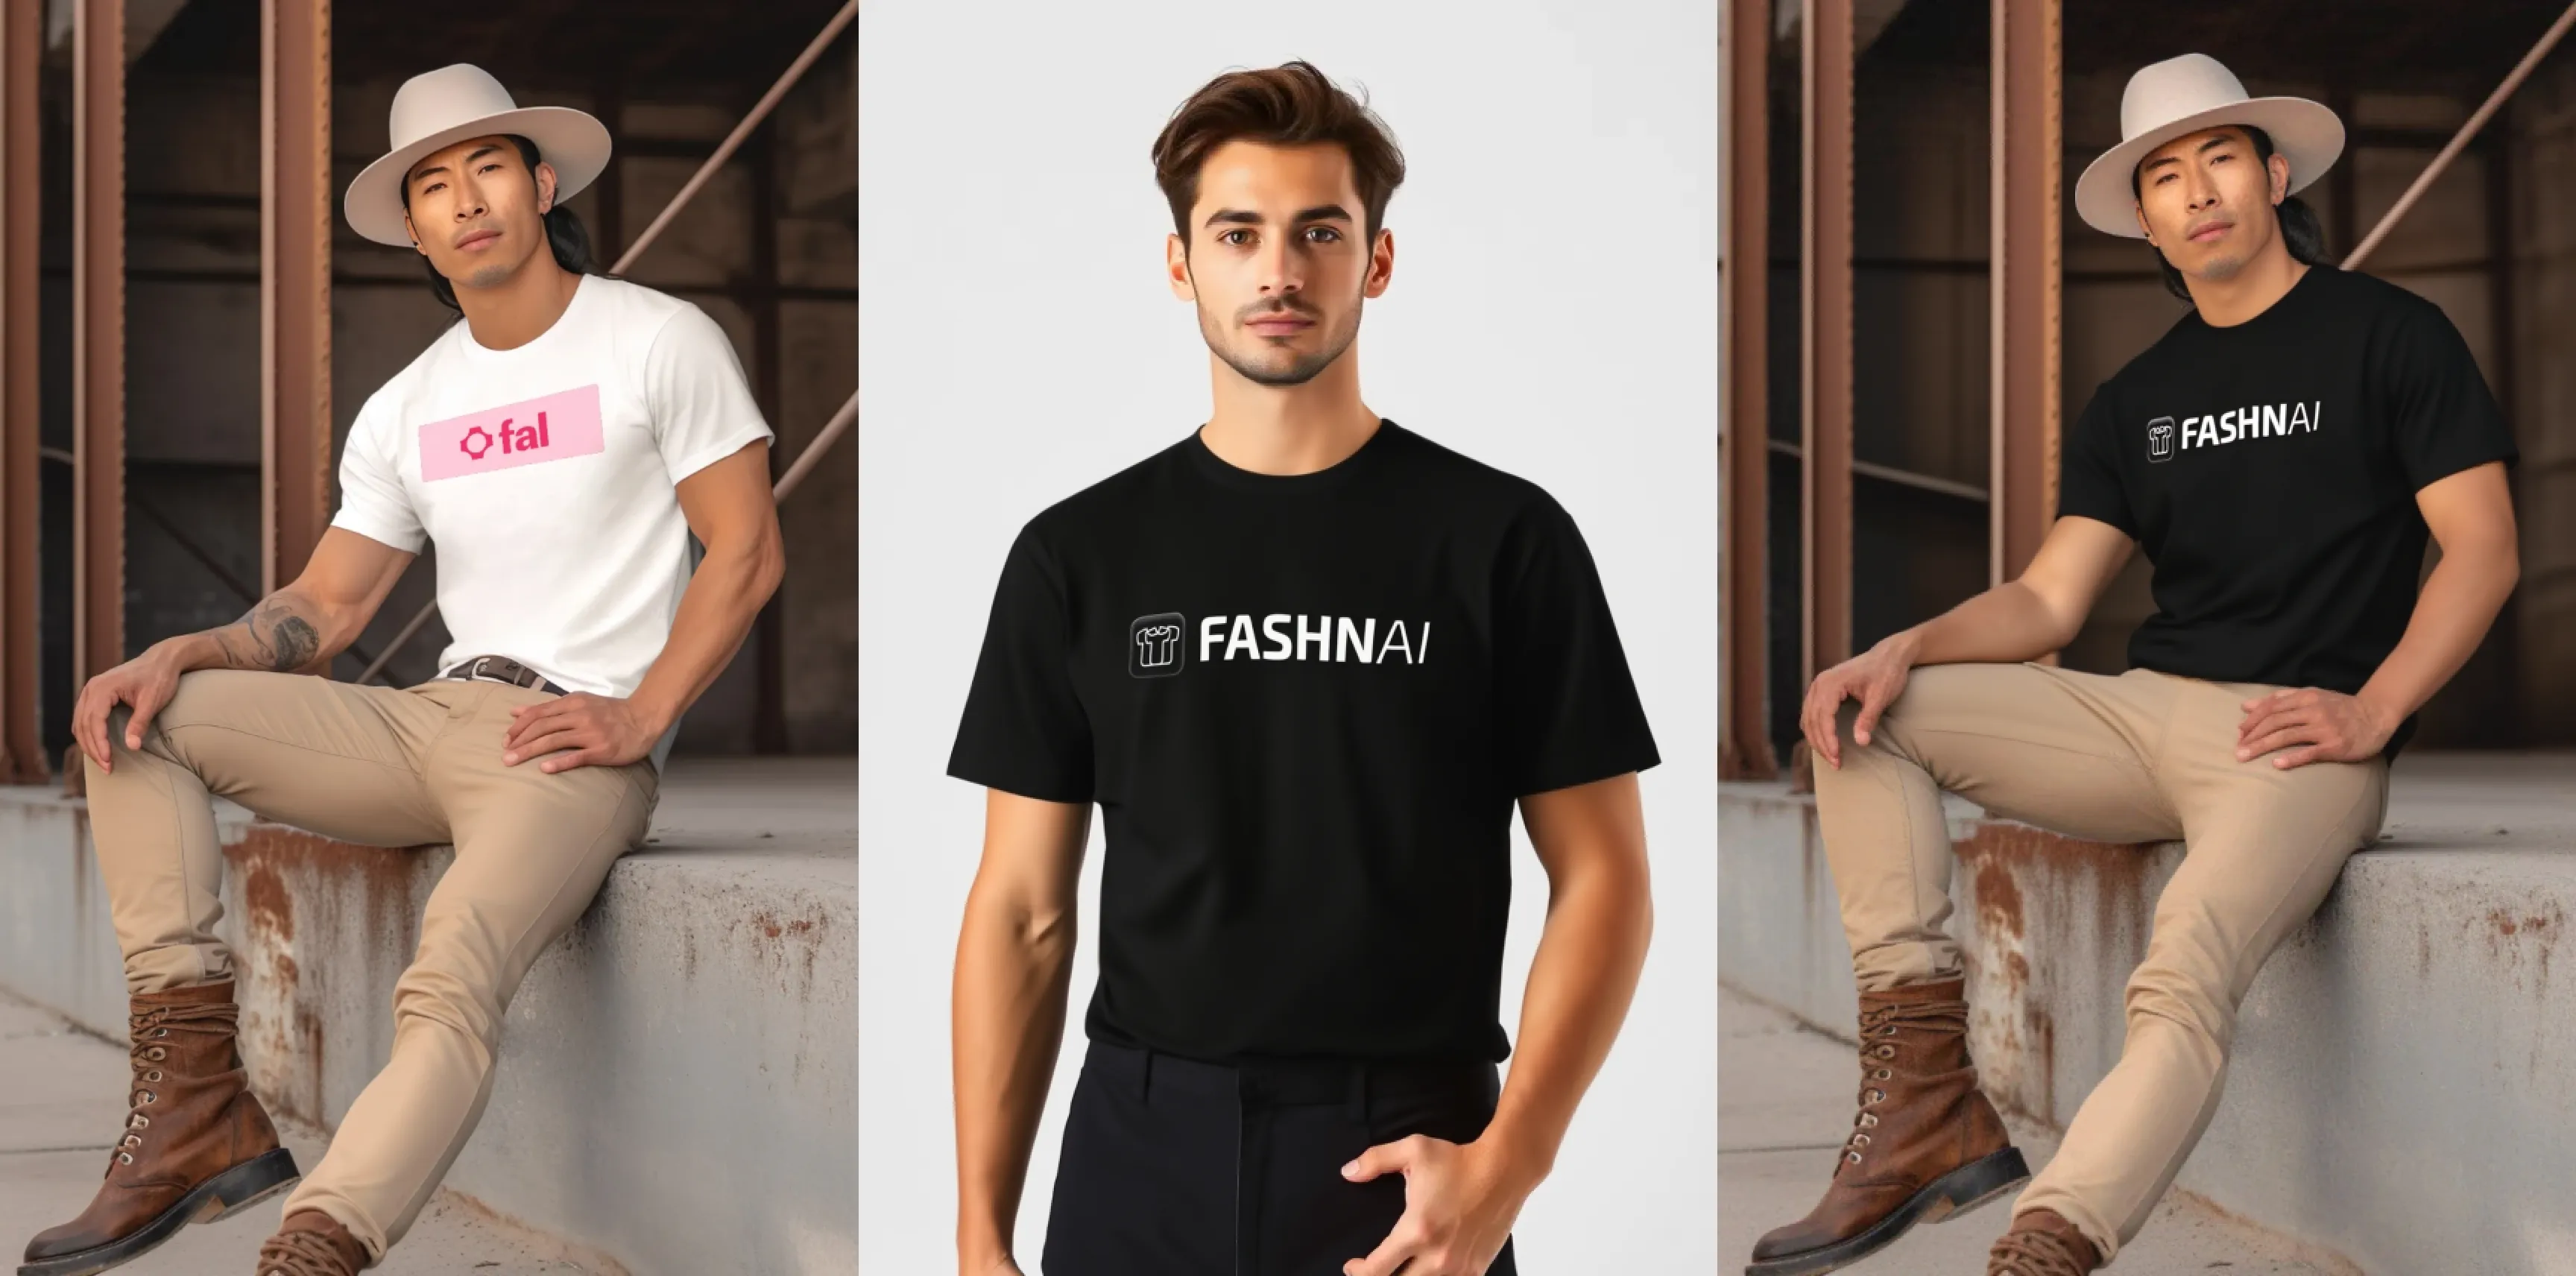 image-to-image
fal-ai/fashn/tryon/v1.6FASHN v1.6 delivers precise virtual try-on capabilities, accurately rendering garment details like text and patterns at 864x1296 resolution from both on-model and flat-lay photo references.