 image-to-image
Object Removal
fal-ai/image-apps-v2/object-removalRemove unwanted objects seamlessly from any image.
Browse the public fal model directory. Models become callable through Kaista Cloud only after supply, pricing, and compatibility review.
image-to-imagefal-ai/image-apps-v2/object-removalRemove unwanted objects seamlessly from any image.
 image-to-image
bria/fibo-edit/blendimage composition model. Combine and blend multiple image parts into complex compositions through natural language and sequential editing.
 image-to-image
bria/fibo-edit/add_object_by_textPrecisely insert new objects into images with structured spatial commands. Context-aware, high-quality editing with seamless blending. Trained on licensed data for risk-free commercial and brand-safe use.
 text-to-video
veed/avatars/text-to-videoGenerate high-quality videos with UGC-like avatars from text
 speech-to-text
kotoba-technologies/kotoba-streaming-stt/v1/realtimeLive transcription over WebSocket, with partial results as the speaker talks.
 image-to-image
fal-ai/flux-general/differential-diffusionA specialized FLUX endpoint combining differential diffusion control with LoRA, ControlNet, and IP-Adapter support, enabling precise, region-specific image transformations through customizable change maps.
 image-to-image
fal-ai/vidu/reference-to-imageVidu Reference-to-Image creates images by using a reference images and combining them with a prompt.
 vision
fal-ai/sa2va/8b/videoSa2VA is an MLLM capable of question answering, visual prompt understanding, and dense object segmentation at both image and video levels
 image-to-image
bria/fibo-edit/replace_object_by_textReplace any object in an image using plain language with fine-grained, precise edits and strong prompt adherence. Trained on licensed data for risk-free commercial and brand-safe use.
 image-to-image
fal-ai/flux-1/dev/image-to-imageFLUX.1 [dev] is a 12 billion parameter flow transformer that generates high-quality images from text. It is suitable for personal and commercial use.
 image-to-image
fal-ai/florence-2-large/dense-region-captionFlorence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks
 text-to-video
fal-ai/pixverse/v5.6/text-to-videoUse the latest pixverse v5.6 model to turn your texts into amazing videos.
 image-to-video
fal-ai/pixverse/v4/effectsGenerate high quality video clips with different effects using PixVerse v4
 image-to-image
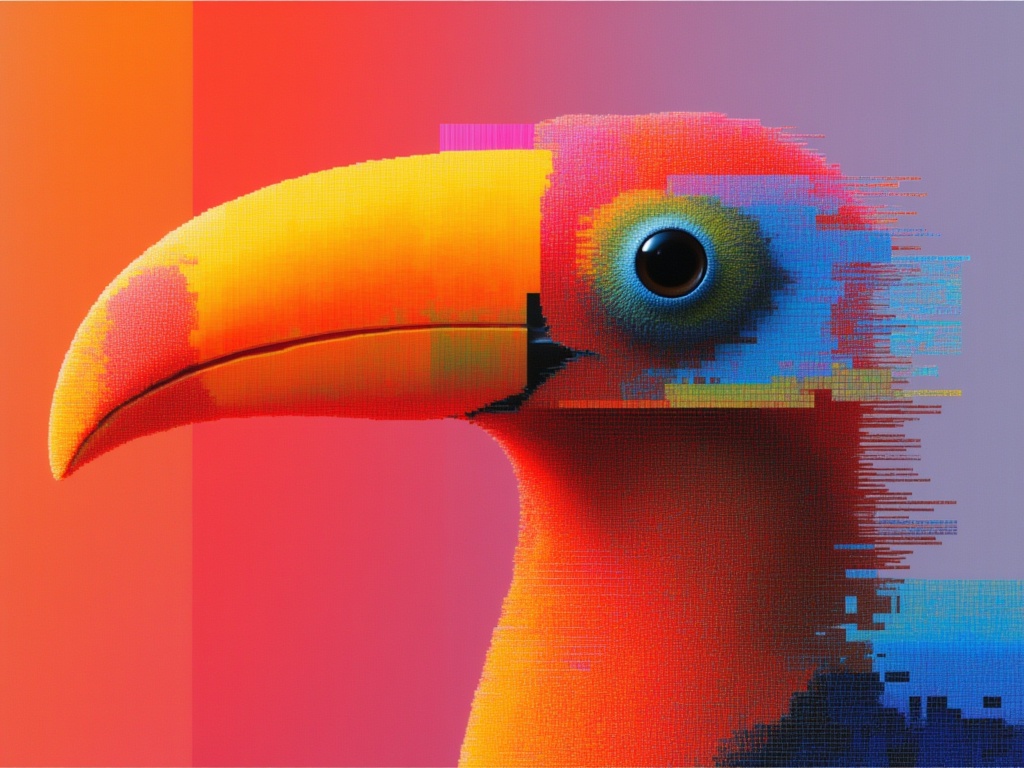
fal-ai/post-processing/grainApply film grain effect with different styles (modern, analog, kodak, fuji, cinematic, newspaper) and customizable intensity and scale
 text-to-audio
mureka/api/generate/speechSynthesizes speech from text using a built-in voice preset or an uploaded custom voice.
 image-to-video
fal-ai/framepack/f1Framepack is an efficient Image-to-video model that autoregressively generates videos.
 text-to-video
fal-ai/kling-video/lipsync/text-to-videoKling LipSync is a text-to-video model that generates realistic lip movements from text input.
 training
fal-ai/ltx23-trainer-v2/t2vFine-tune LTX 2.3 on your own clips to teach it a new subject, character, object, or visual style, then generate full videos from a text prompt.
 speech-to-speech
kotoba-technologies/kotoba-sts/v1/realtime_voiceSpeak in one language, hear it in another. Streaming speech-to-speech translation with the translated text alongside the audio.
 image-to-image
fal-ai/image-apps-v2/city-teleportPlace a person’s photo into iconic cities worldwide.
 text-to-video
fal-ai/ltx-2.3-22b/text-to-video/loraGenerate video with audio from text using LTX-2.3 and custom LoRA
 training
fal-ai/trellis-2-lora-trainerTrain LoRA adapters for TRELLIS.2 model
 image-to-image
bria/fibo-edit/restyleProduction-grade style transfer that maps photos to distinct artistic styles using curated, brand-safe presets. Trained exclusively on licensed data for risk-free commercial use.
 image-to-image
fal-ai/qwen-image-edit-plus-lora-gallery/shirt-designApply designs/graphics onto people's shirts
 image-to-video
fal-ai/pixverse/v5.6/transitionUse the latest pixverse v5.6 model to turn your texts and images into amazing videos.
 text-to-image
fal-ai/wan/v2.2-5b/text-to-imageWan 2.2's 5B model generates high-resolution, photorealistic images with powerful prompt understanding and fine-grained visual detail
 image-to-image
fal-ai/emu-3.5-image/edit-imageEdit images with a text prompt using Emu 3.5 Image
 training
fal-ai/ltx23-trainer-v2/t2aTrain a LoRA that generates audio from a text prompt — the audio counterpart of text-to-video — learning a sound or style from your clips.