 text-to-audio
Stable Audio 2.5
fal-ai/stable-audio-25/text-to-audioGenerate high quality music and sound effects using Stable Audio 2.5 from StabilityAI
Browse the public fal model directory. Models become callable through Kaista Cloud only after supply, pricing, and compatibility review.
text-to-audiofal-ai/stable-audio-25/text-to-audioGenerate high quality music and sound effects using Stable Audio 2.5 from StabilityAI
 video-to-video
fal-ai/sync-lipsync/v2Generate realistic lipsync animations from audio using advanced algorithms for high-quality synchronization with Sync Lipsync 2.0 model
 text-to-image
blackforestlabs/flux-3/text-to-imageFLUX 3 Image is Black Forest Labs' newest image model. Generate detailed, well-composed images in native 2K and 4K with precise layout control and improved text rendering.
 image-to-image
fal-ai/clarity-upscalerClarity upscaler for upscaling images with high very fidelity.
 image-to-image
topaz/upscale/image/precisionProfessional photo upscaling powered by Topaz Labs. Gigapixel precision models (Standard V2, High Fidelity, Low Resolution, CGI, Text Refine) enlarge images faithfully up to 4x. Best for photos that must stay true to the original.
 image-to-video
fal-ai/bytedance/omnihuman/v1.5Omnihuman v1.5 is a new and improved version of Omnihuman. It generates video using an image of a human figure paired with an audio file. It produces vivid, high-quality videos where the character’s emotions and movements maintain a strong correlation with the audio.
 video-to-video
fal-ai/bytedance-upscaler/upscale/videoUpscale videos with Bytedance's video upscaler.
 video-to-video
kling/v4/video-to-video/editKling 4.0 edits an input video using text instructions and optional image references, producing 3 to 30-second videos at 720p or 1080p.
 image-to-3d
tripo3d/h3.1/image-to-3dGenerate high-quality 3D models from a single image using Tripo H3.1.
 text-to-image
meta/muse-image/text-to-imageMeta's Muse Image model has faithful instruction-following and exceptional visual fidelity, with fine details like text, plots, and QR codes rendered accurately.
 image-to-image
xai/grok-imagine-image/v2.0/editEdit images with xAi's Grok Imagine 2.0 model.
 text-to-speech
fal-ai/elevenlabs/tts/turbo-v2.5Generate high-speed text-to-speech audio using ElevenLabs TTS Turbo v2.5.
 video-to-video
alibaba/wan-3.0-prime/reference-to-videoWan 3.0 Prime Reference-to-Video combines reference images, videos, and audio into a unified video with fast generation and strong multimodal coherence. It follows character identity, visual style, movement, and sound cues across references to create controlled, consistent, and production-ready results.
 image-to-image
blackforestlabs/flux-3/klein/edit-imageEdits and composes images from text instructions and up to ten references with FLUX.3 Klein, with optional bounding-box controls for object placement and transformation.
 image-to-image
fal-ai/flux-2/klein/9b/editImage-to-image editing with FLUX.2 [klein] 9B from Black Forest Labs. Precise modifications using natural language descriptions and hex color control.
 video-to-video
topaz/upscale/video/precisionProfessional video upscaling powered by Topaz Labs. Precision models (Proteus, Artemis, Iris, Dione, Theia, Gaia, Rhea) enhance footage up to 4x while staying faithful to the source. Best for clean, natural upscales of real-world footage.
 text-to-video
blackforestlabs/flux-3-max/text-to-videofal’s FLUX 3 Max is a post-trained variant of FLUX 3 Video, tuned for stronger prompt adherence and better visual quality while optimized for lower latency.
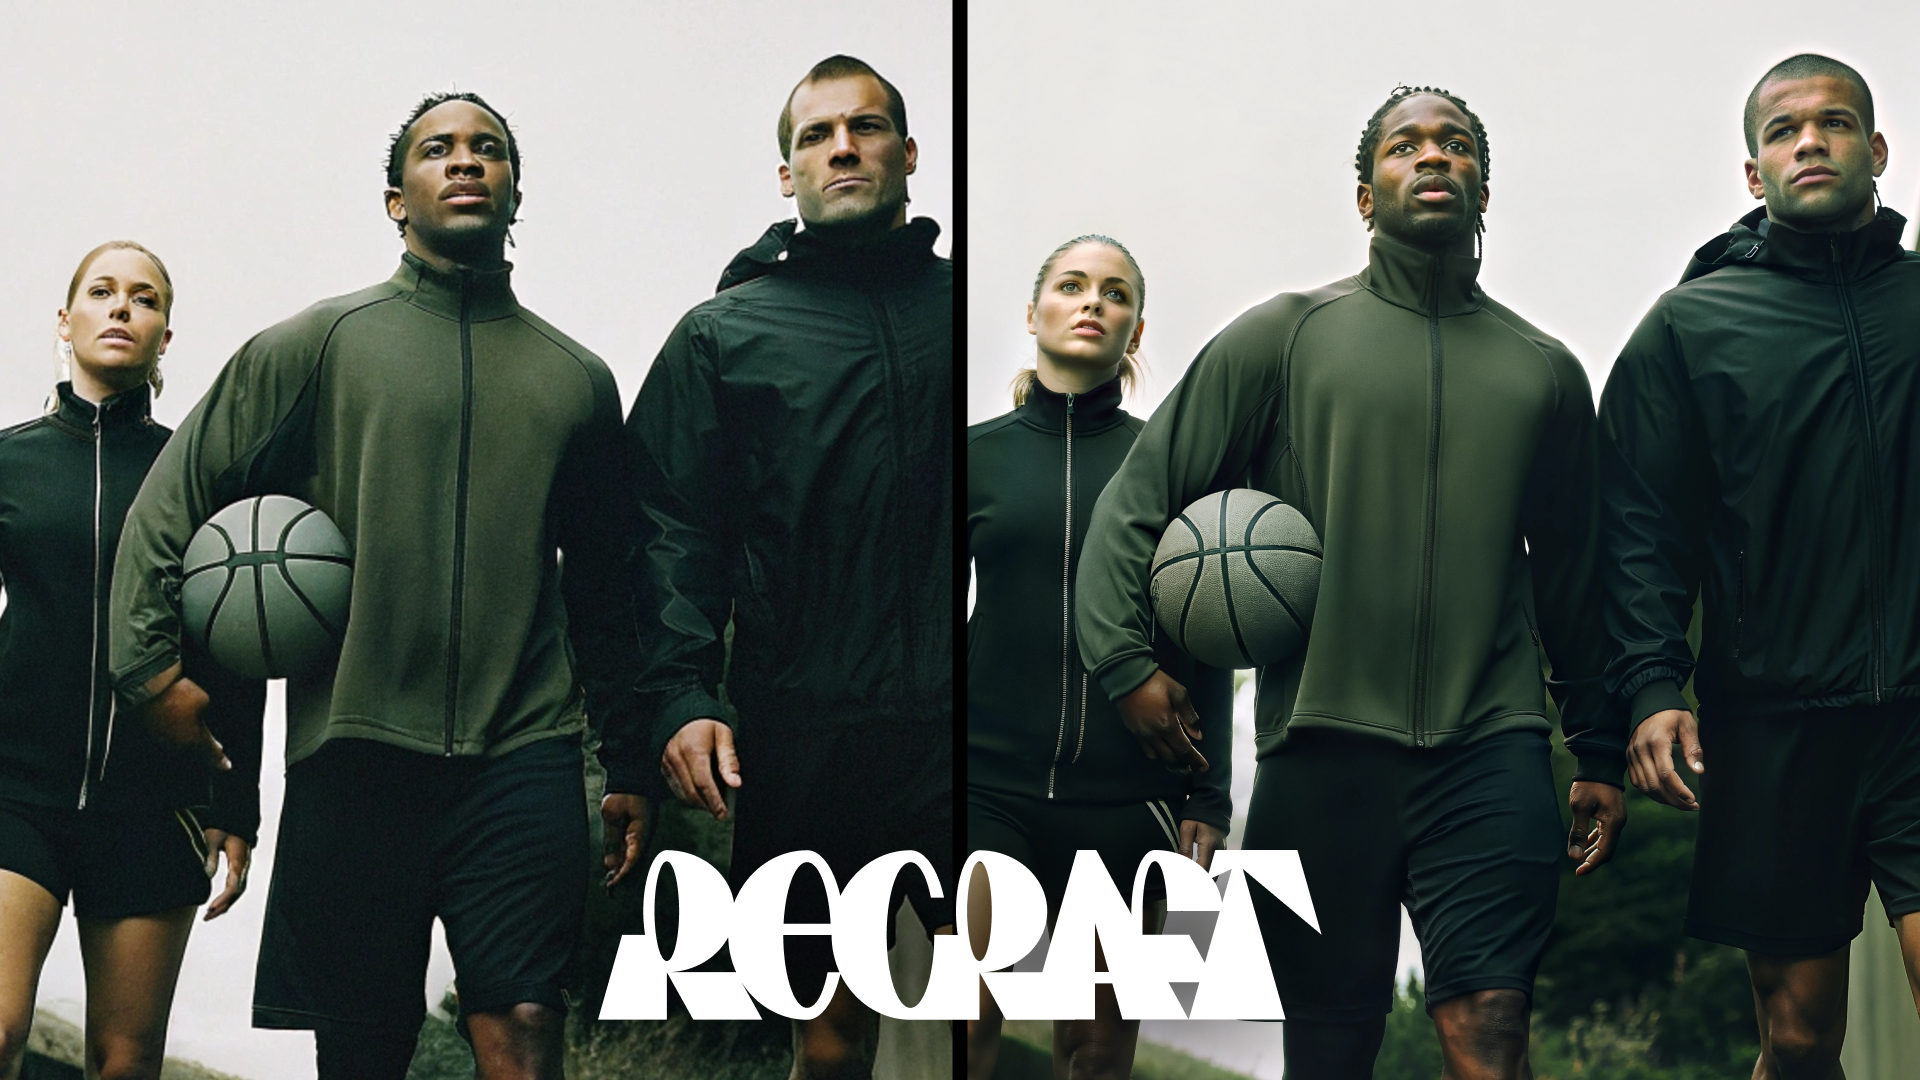 image-to-image
fal-ai/recraft/upscale/crispEnhances a given raster image using 'crisp upscale' tool, boosting resolution with a focus on refining small details and faces.
 image-to-image
ideogram/v4.5/editEdit images with Ideogram 4.5: prompt edits with up to 4 reference images, optional mask, and a high-precision mode that keeps unchanged pixels intact.
 video-to-video
fal-ai/sync-lipsync/v2/proGenerate high-quality realistic lipsync animations from audio while preserving unique details like natural teeth and unique facial features using the state-of-the-art Sync Lipsync 2 Pro model.
 text-to-video
fal-ai/kling-video/v3/pro/text-to-videoKling 3.0 Pro: Top-tier text-to-video with cinematic visuals, fluid motion, and native audio generation, with multi-shot support.
 image-to-video
bytedance/seedance-2.0/fast/image-to-videoByteDance's most advanced image-to-video model, fast tier. Lower latency and cost with synchronized audio, start and end frame control, and motion prompts.
 image-to-video
fal-ai/kling-video/o3/pro/image-to-videoGenerate a video by taking a start frame and an end frame, animating the transition between them while following text-driven style and scene guidance.
 image-to-video
xai/grok-imagine-video/image-to-videoGenerate videos from images with audio using xAI's Grok Imagine Video model.
 image-to-video
fal-ai/kling-video/v2.5-turbo/standard/image-to-videoKling 2.5 Turbo Standard: Top-tier image-to-video generation with unparalleled motion fluidity, cinematic visuals, and exceptional prompt precision.
 text-to-image
xai/grok-imagine-imageGenerate highly aesthetic images with xAI's Grok Imagine Image generation model.
 image-to-image
google/nano-banana-lite/editNano banana lite is the efficiency-focused model in the image generation family. Sub-2 second latency with cost-effective generation and editing, fast multi-turn local edits, and 14 supported aspect ratios.
 text-to-image
google/nano-banana-2-liteNano banana lite is the efficiency-focused model in the image generation family. Sub-2 second latency with cost-effective generation and editing, fast multi-turn local edits, and 14 supported aspect ratios.