 text-to-video
Hunyuan Video V1.5
fal-ai/hunyuan-video-v1.5/text-to-videoHunyuan Video 1.5 is Tencent's latest and best video model
Browse the public fal model directory. Models become callable through Kaista Cloud only after supply, pricing, and compatibility review.
text-to-videofal-ai/hunyuan-video-v1.5/text-to-videoHunyuan Video 1.5 is Tencent's latest and best video model
 image-to-video
fal-ai/vidu/q2/image-to-video/proUse the latest Vidu Q2 models which much more better quality and control on your videos.
 image-to-image
fal-ai/longcat-image/editLongCat image Edit is a 6B parameter image editing model excelling at multilingual text rendering, photorealism and deployment efficiency.
 text-to-image
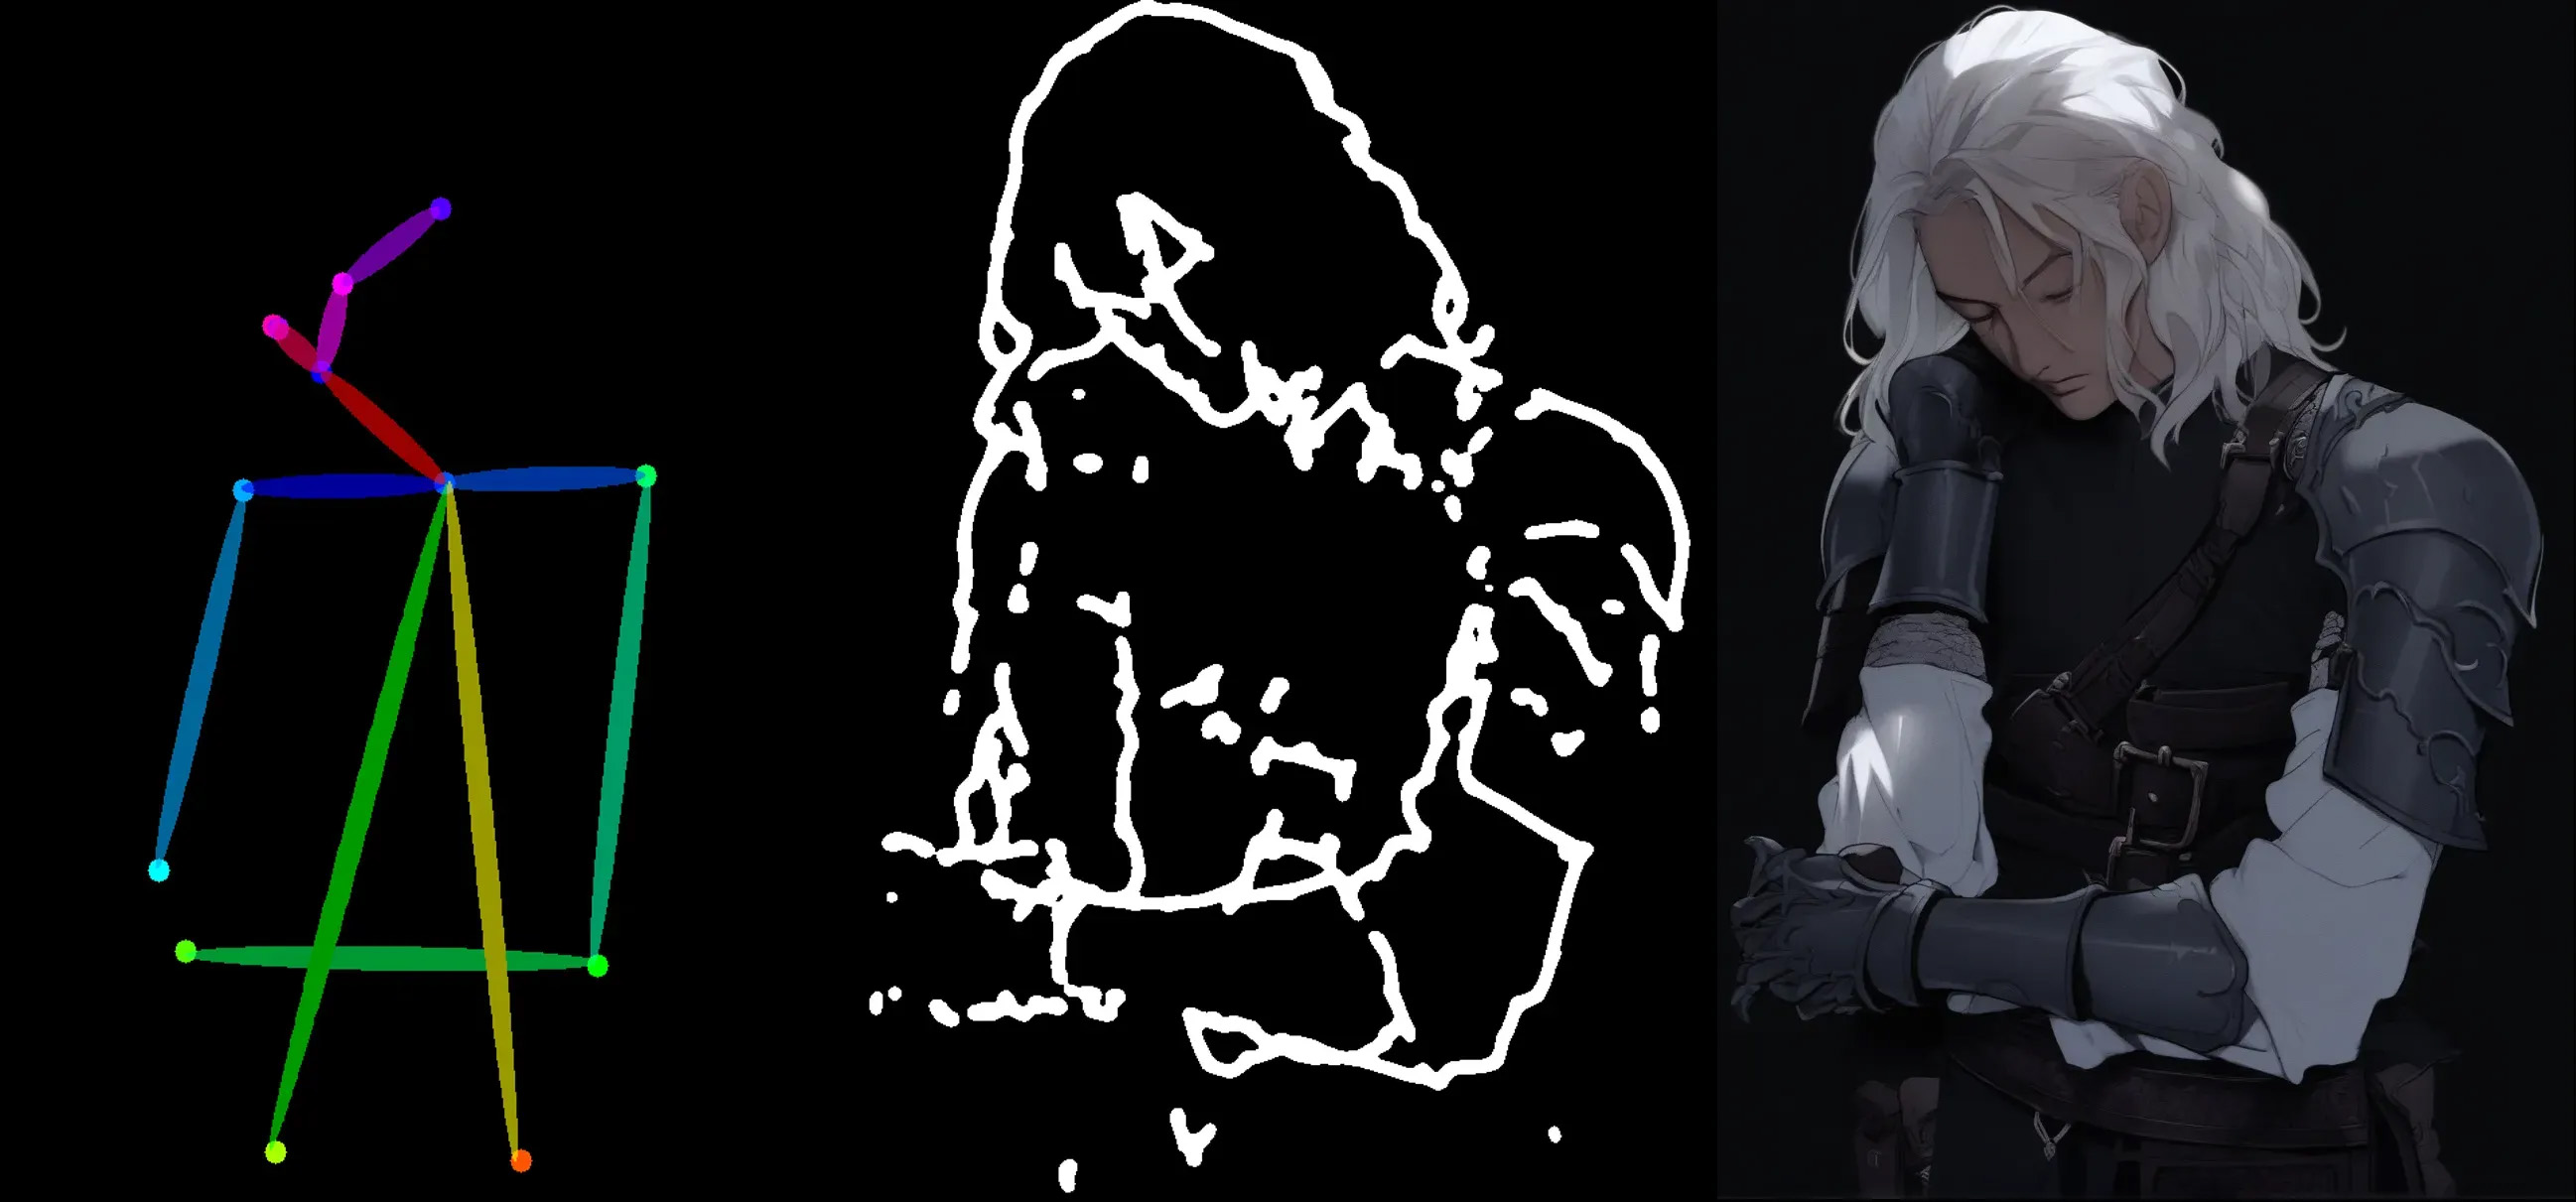
fal-ai/sdxl-controlnet-unionAn efficent SDXL multi-controlnet text-to-image model.
 image-to-image
fal-ai/stable-diffusion-v3-medium/image-to-imageStable Diffusion 3 Medium (Image to Image) is a Multimodal Diffusion Transformer (MMDiT) model that improves image quality, typography, prompt understanding, and efficiency.
 text-to-image
fal-ai/hunyuan-image/v2.1/text-to-imageUse the amazing capabilities of hunyuan image 2.1 to generate images that express the feelings of your text.
 image-to-image
fal-ai/rifeInterpolate images with RIFE - Real-Time Intermediate Flow Estimation
 text-to-image
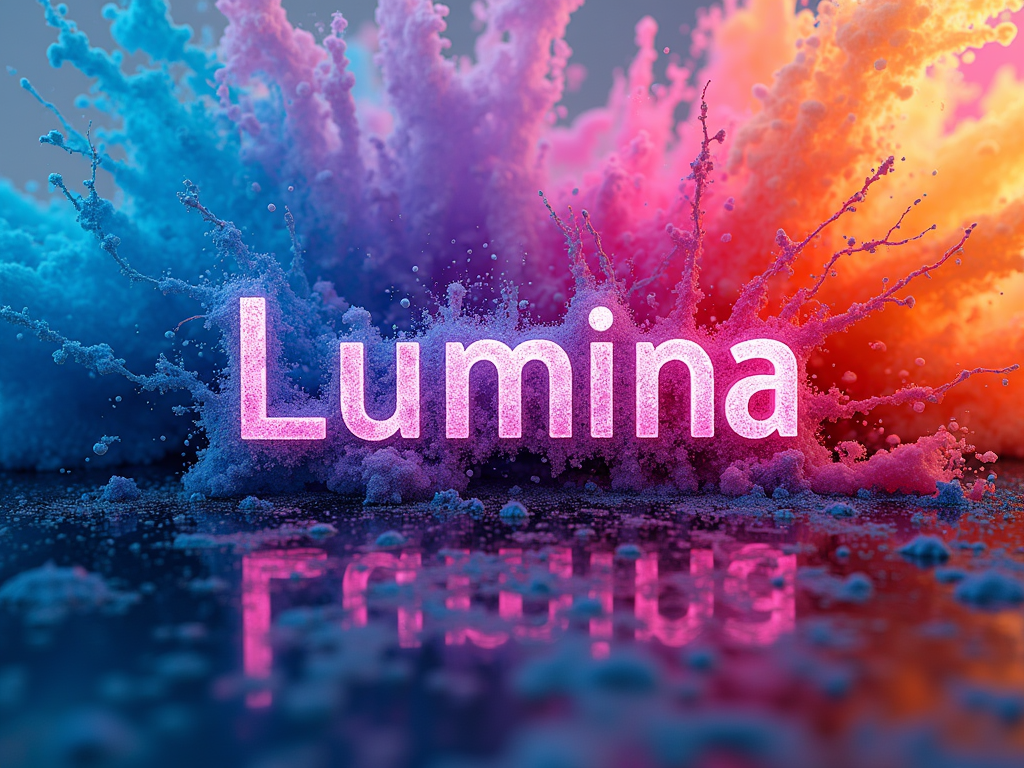
fal-ai/lumina-image/v2Lumina-Image-2.0 is a 2 billion parameter flow-based diffusion transforer which features improved performance in image quality, typography, complex prompt understanding, and resource-efficiency.
 image-to-video
fal-ai/kandinsky6-lite/image-to-videoKandinsky 6.0 Lite animates a single image into a short video clip, with fast, lightweight inference and prompt-guided motion.
 text-to-video
fal-ai/minimax/hailuo-02/pro/text-to-videoMiniMax Hailuo-02 Text To Video API (Pro, 1080p): Advanced video generation model with 1080p resolution
 text-to-image
fal-ai/luma-photon/flashGenerate images from your prompts using Luma Photon Flash. Photon Flash is the most creative, personalizable, and intelligent visual models for creatives, bringing a step-function change in the cost of high-quality image generation.
 video-to-video
fal-ai/infinitalk/video-to-videoInfinitalk model generates a talking avatar video from an image and audio file. The avatar lip-syncs to the provided audio with natural facial expressions.
 3d-to-3d
fal-ai/trellis-2/retextureRetexture existing 3D models using images with Trellis 2
 text-to-image
fal-ai/ideogram/v2a/turboAccelerated image generation with Ideogram V2A Turbo. Create high-quality visuals, posters, and logos with enhanced speed while maintaining Ideogram's signature quality.
 image-to-image
fal-ai/qwen-image-edit-2509-loraLoRA endpoint for the Qwen Image Edit 2509 model.
 image-to-image
fal-ai/flux/dev/reduxFLUX.1 [dev] Redux is a high-performance endpoint for the FLUX.1 [dev] model that enables rapid transformation of existing images, delivering high-quality style transfers and image modifications with the core FLUX capabilities.
 text-to-image
fal-ai/recraft/v4.1/utility/pro/text-to-imageRecraft V4.1 Utility Pro pairs the high-resolution output of V4.1 Pro with a faster, cost-efficient runtime. Designed for studios shipping large-format work at scale, it makes premium-quality raster generation viable across full creative pipelines.
 video-to-video
veed/video-background-removal/green-screenRemove background from videos filmed using chromakey, with automatic green spill suppression for clean, professional edges.
image-to-imagefal-ai/florence-2-large/referring-expression-segmentationFlorence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks
 text-to-image
rundiffusion-fal/juggernaut-flux/proJuggernaut Pro Flux by RunDiffusion is the flagship Juggernaut model rivaling some of the most advanced image models available, often surpassing them in realism. It combines Juggernaut Base with RunDiffusion Photo and features enhancements like reduced background blurriness.
 text-to-image
bria/fibo-gen-1.5/text-to-imageText-to-image model with high-fidelity outputs, accurate typography, and style preset, strong in photorealism, textures, and beyond. JSON-structured prompts give enterprise and agentic workflows production-ready control. Trained on licensed data.
 image-to-image
fal-ai/flux-krea-lora/image-to-imageFLUX LoRA Image-to-Image is a high-performance endpoint that transforms existing images using FLUX models, leveraging LoRA adaptations to enable rapid and precise image style transfer, modifications, and artistic variations.
 video-to-audio
fal-ai/sam-audio/visual-separateAudio separation with SAM Audio. Isolate any sound using natural language—professional-grade audio editing made simple for creators, researchers, and accessibility applications.
 audio-to-video
pixverse/music-video/vibemvPixVerse VibeMV generates music videos from audio, with optional character references and lyric subtitles. It supports visual style presets, custom style references, five aspect ratios, and output at 720p or 1080p.
 image-to-video
fal-ai/davinci-magihumanExpressive facial performance, natural speech-expression coordination, realistic body motion, and accurate audio-video synchronization with DaVinci-MagiHuman model
 audio-to-audio
fal-ai/stable-audio-3/small/sfx/audio-to-audioStable Audio 3 Small SFX audio-to-audio is a 459 million parameter latent diffusion model that transforms input audio into new sound-effect variations guided by text prompts.
 image-to-video
fal-ai/wan-pro/image-to-videoWan-2.1 Pro is a premium image-to-video model that generates high-quality 1080p videos at 30fps with up to 6 seconds duration, delivering exceptional visual quality and motion diversity from images
 speech-to-text
fal-ai/speech-to-textLeverage the rapid processing capabilities of AI models to enable accurate and efficient real-time speech-to-text transcription.