 text-to-audio
MiniMax (Hailuo AI) Music
fal-ai/minimax-musicGenerate music from text prompts using the MiniMax model, which leverages advanced AI techniques to create high-quality, diverse musical compositions.
Browse the public fal model directory. Models become callable through Kaista Cloud only after supply, pricing, and compatibility review.
text-to-audiofal-ai/minimax-musicGenerate music from text prompts using the MiniMax model, which leverages advanced AI techniques to create high-quality, diverse musical compositions.
 training
fal-ai/z-image-turbo-trainer-v2Fast LoRA trainer for Z-Image-Turbo, a super fast text-to-image model of 6B parameters developed by Tongyi-MAI.
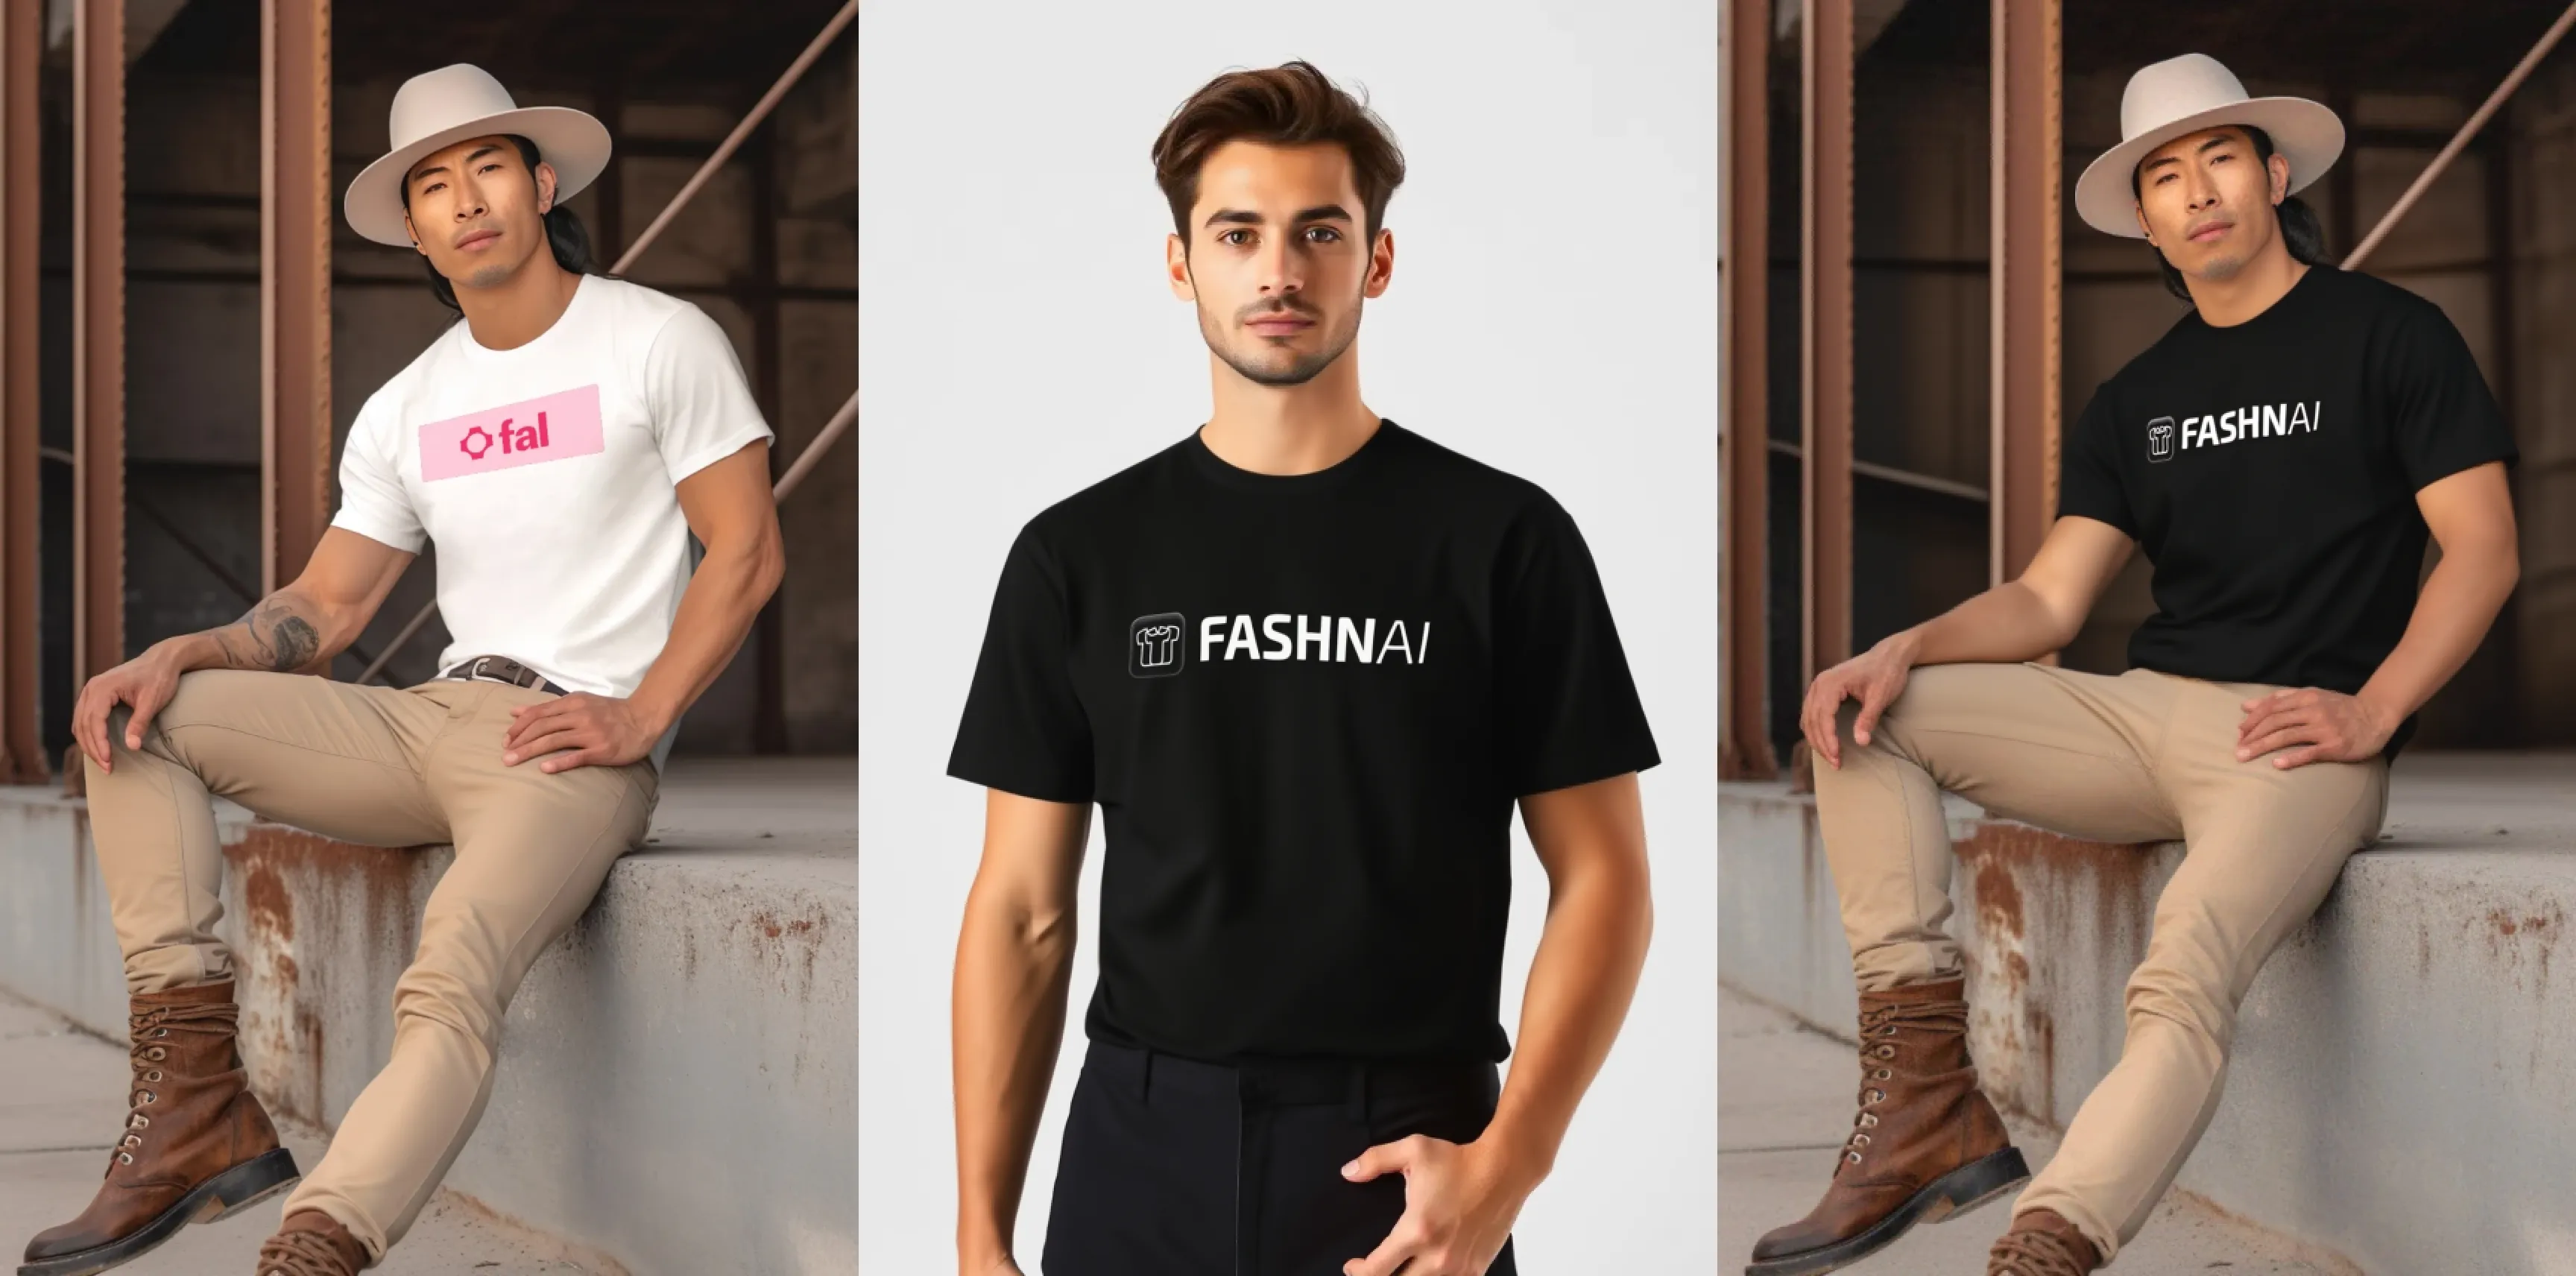 image-to-image
fal-ai/fashn/tryon/v1.5FASHN v1.5 delivers precise virtual try-on capabilities, accurately rendering garment details like text and patterns at 576x864 resolution from both on-model and flat-lay photo references.
 video-to-video
fal-ai/kling-video/o1/video-to-video/referenceKling O1 Omni generates new shots guided by an input reference video, preserving cinematic language such as motion, and camera style to produce seamless scene continuity.
 video-to-video
fal-ai/ltx-2.3-quality/render-to-realTransform your 3D video render into realistic using first frame with Ltx 2.3
 text-to-video
 image-to-video
veed/fabric-1.0/fastVEED Fabric 1.0 is an image-to-video API that turns any image into a talking video
 text-to-audio
fal-ai/minimax-music/v1.5Generate music from text prompts using the MiniMax model, which leverages advanced AI techniques to create high-quality, diverse musical compositions.
 image-to-image
fal-ai/image-apps-v2/photo-restorationRestore old or damaged photos by fixing colors, scratches, and resolution.
 video-to-video
fal-ai/wan-22-vace-fun-a14b/depthVACE Fun for Wan 2.2 A14B from Alibaba-PAI
 image-to-video
fal-ai/kling-video/v1/pro/ai-avatarKling AI Avatar Pro: The premium endpoint for creating avatar videos with realistic humans, animals, cartoons, or stylized characters
 image-to-image
fal-ai/minimax/image-01/subject-referenceGenerate images from text and a reference image using MiniMax Image-01 for consistent character appearance.
 3d-to-3d
tripo3d/tripo/remeshConverts triangle meshes into clean quad topology at a target polygon count, animation-ready with no manual retopology.
 text-to-image
fal-ai/ernie-image/turboHigh-quality text-to-image model by Baidu. Supports English, Chinese, and Japanese prompts with built-in prompt expansion.
 image-to-image
fal-ai/bria/genfillBria GenFill enables high-quality object addition or visual transformation. Trained exclusively on licensed data for safe and risk-free commercial use. Access the model's source code and weights: https://bria.ai/contact-us
 image-to-video
fal-ai/ltxv-13b-098-distilled/image-to-videoGenerate long videos from prompts and images using LTX Video-0.9.8 13B Distilled and custom LoRA
 image-to-image
 text-to-video
alibaba/happy-horse/v1.1/text-to-videoHappy Horse 1.1 is Alibaba's #1-ranked video model. This text-to-video endpoint generates 1080p video with synchronized native audio and multilingual lip-sync from a text prompt alone.
 video-to-video
fal-ai/heygen/v2/translate/speedHeygen Translate Model with Extreme Speed
 image-to-json
bria/ad-delayerTurn any flat ad image into fully editable layers —background, product and logo cutouts, live text with typography, and vector shapes. Commercial-safe, structured JSON output
 image-to-image
fal-ai/filmInterpolate images with FILM - Frame Interpolation for Large Motion
 image-to-image
fal-ai/phota/enhanceEnhance images while preserving identities with Phota
image-to-imagefal-ai/instant-characterInstantCharacter creates high-quality, consistent characters from text prompts, supporting diverse poses, styles, and appearances with strong identity control.
 image-to-image
fal-ai/retoucherAutomatically retouches faces to smooth skin and remove blemishes.
 text-to-image
microsoft/mai-image-2.5-proGenerate high-fidelity, design-ready images with precise typography, strong prompt alignment, and rich visual detail using Microsoft's flagship MAI Image 2.5 Pro.
 image-to-image
krea/v3/realtimeEdits an input image in a realtime session using text prompts, with seed control.
 training
fal-ai/qwen-image-2512-trainerQwen Image 2512 LoRA training
 text-to-speech
fal-ai/minimax/speech-2.6-turboGenerate speech from text prompts and different voices using the MiniMax Speech-2.6 HD model, which leverages advanced AI techniques to create high-quality text-to-speech.