 video-to-video
Motion To Code
fal-ai/motion-to-code/gsapTurn a prompt, an image or a reference video into an editable GSAP animation: one self-contained HTML page you can play, tweak and ship.
Browse the public fal model directory. Models become callable through Kaista Cloud only after supply, pricing, and compatibility review.
video-to-videofal-ai/motion-to-code/gsapTurn a prompt, an image or a reference video into an editable GSAP animation: one self-contained HTML page you can play, tweak and ship.
 image-to-video
fal-ai/minimax/hailuo-2.3/standard/image-to-videoMiniMax Hailuo-2.3 Image To Video API (Standard, 768p): Advanced image-to-video generation model with 768p resolution
 image-to-video
lightricks/ltx-2.5/image-to-video/proLTX-2.5 is Lightricks' open-source audio-video model. This endpoint animates a still image into video with synchronized audio in a single pass, in a quality-optimized mode for high-fidelity final output.
 video-to-video
fal-ai/wan/v2.2-14b/animate/moveWan-Animate is a video model that generates high-fidelity character videos by replicating the expressions and movements of characters from reference videos.
 image-to-image
bria/increase-resolutionUpscale any image 2x or 4x, up to 8192×8192, with Bria Increase Resolution. Preserves the original content — no regeneration, no altered details. Commercial-safe
 text-to-video
fal-ai/kling-video/o3/pro/text-to-videoGenerate realistic videos using Kling O3 from Kling Team!
 video-to-video
fal-ai/bytedance/dreamactor/v2Transfer motion from a video to characters in an image using Dreamactor v2. Great performance for non-human and multiple characters
 training
fal-ai/krea-2-trainerTrain a custom LoRA on your own images to teach Krea 2 a new subject, character, or style. Provide a set of training images (and an optional trigger word), and the trainer outputs LoRA weights you can use for inference with the Krea 2 LoRA endpoint.
 text-to-image
fal-ai/flux-2-flexText-to-image generation with FLUX.2 [flex] from Black Forest Labs. Features adjustable inference steps and guidance scale for fine-tuned control. Enhanced typography and text rendering capabilities.
 video-to-video
fal-ai/kling-video/o3/pro/video-to-video/referenceKling O3 Omni generates new shots guided by an input reference video, preserving cinematic language such as motion, and camera style to produce seamless scene continuity.
 text-to-image
xai/grok-imagine-image/quality/text-to-imageGrok Imagine Pro is an advanced AI model from xAI that creates high-quality visuals from text prompts and allows you to edit or analyze existing images.
 text-to-audio
 image-to-3d
fal-ai/meshy/v6/image-to-3dMeshy-6 is the latest model from Meshy. It generates realistic and production ready 3D models.
 vision
fal-ai/moondream3-preview/detectMoondream 3 is a vision language model that brings frontier-level visual reasoning with native object detection, pointing, and OCR capabilities to real-world applications requiring fast, inexpensive inference at scale.
 text-to-image
fal-ai/qwen-image-2512Qwen Image 2512 is an improved version of Qwen Image with better text rendering, finer natural textures, and more realistic human generation.
 text-to-video
xai/grok-imagine-video/v1.5/text-to-videoGenerate videos from prompts with audio using xAI's Grok Imagine 1.5 Video model.
 video-to-video
veed/video-background-removal/fastRemove background from any video with people and objects. No green screen needed.
 text-to-video
google/gemini-omni-flashCreates video with synchronized audio from text input. Grounded in Gemini's real-world knowledge, with improved physics understanding for more coherent motion and interaction.
 text-to-image
google/nano-banana-liteNano banana lite is the efficiency-focused model in the image generation family. Sub-2 second latency with cost-effective generation and editing, fast multi-turn local edits, and 14 supported aspect ratios.
 text-to-image
fal-ai/flux-2/loraText-to-image generation with LoRA support for FLUX.2 [dev] from Black Forest Labs. Custom style adaptation and fine-tuned model variations.
 text-to-image
fal-ai/gemini-3.1-flash-image-previewGemini 3.1 Flash Image (a.k.a Nano Banana 2) is Google's new state-of-the-art fast image generation and editing model
 video-to-video
fal-ai/rife/videoInterpolate videos with RIFE - Real-Time Intermediate Flow Estimation
 image-to-image
fal-ai/image-apps-v2/outpaintDirectional outpainting. Choose edges to expand. left, right, top, or center (uniform all sides). Only expanded areas are generated; an optional zoom-out pulls the frame back by the chosen amount.
 image-to-video
google/gemini-omni-flash/reference-to-videoGenerates video with audio from combined multimodal references. Accepts text, images, audio, and video together as input to guide subject, motion, style, and sound in the output.
 image-to-image
fal-ai/wan/v2.7/editTransform and edit existing images with text-guided instructions using the WAN 2.7 model for creative image manipulation.
 video-to-video
fal-ai/wan/v2.7/edit-videoWan 2.7 is the latest generation AI video model, delivering enhanced motion smoothness, superior scene fidelity, and greater visual coherence.
 text-to-video
fal-ai/kling-video/o3/standard/text-to-videoGenerate realistic videos using Kling O3 from Kling Team!
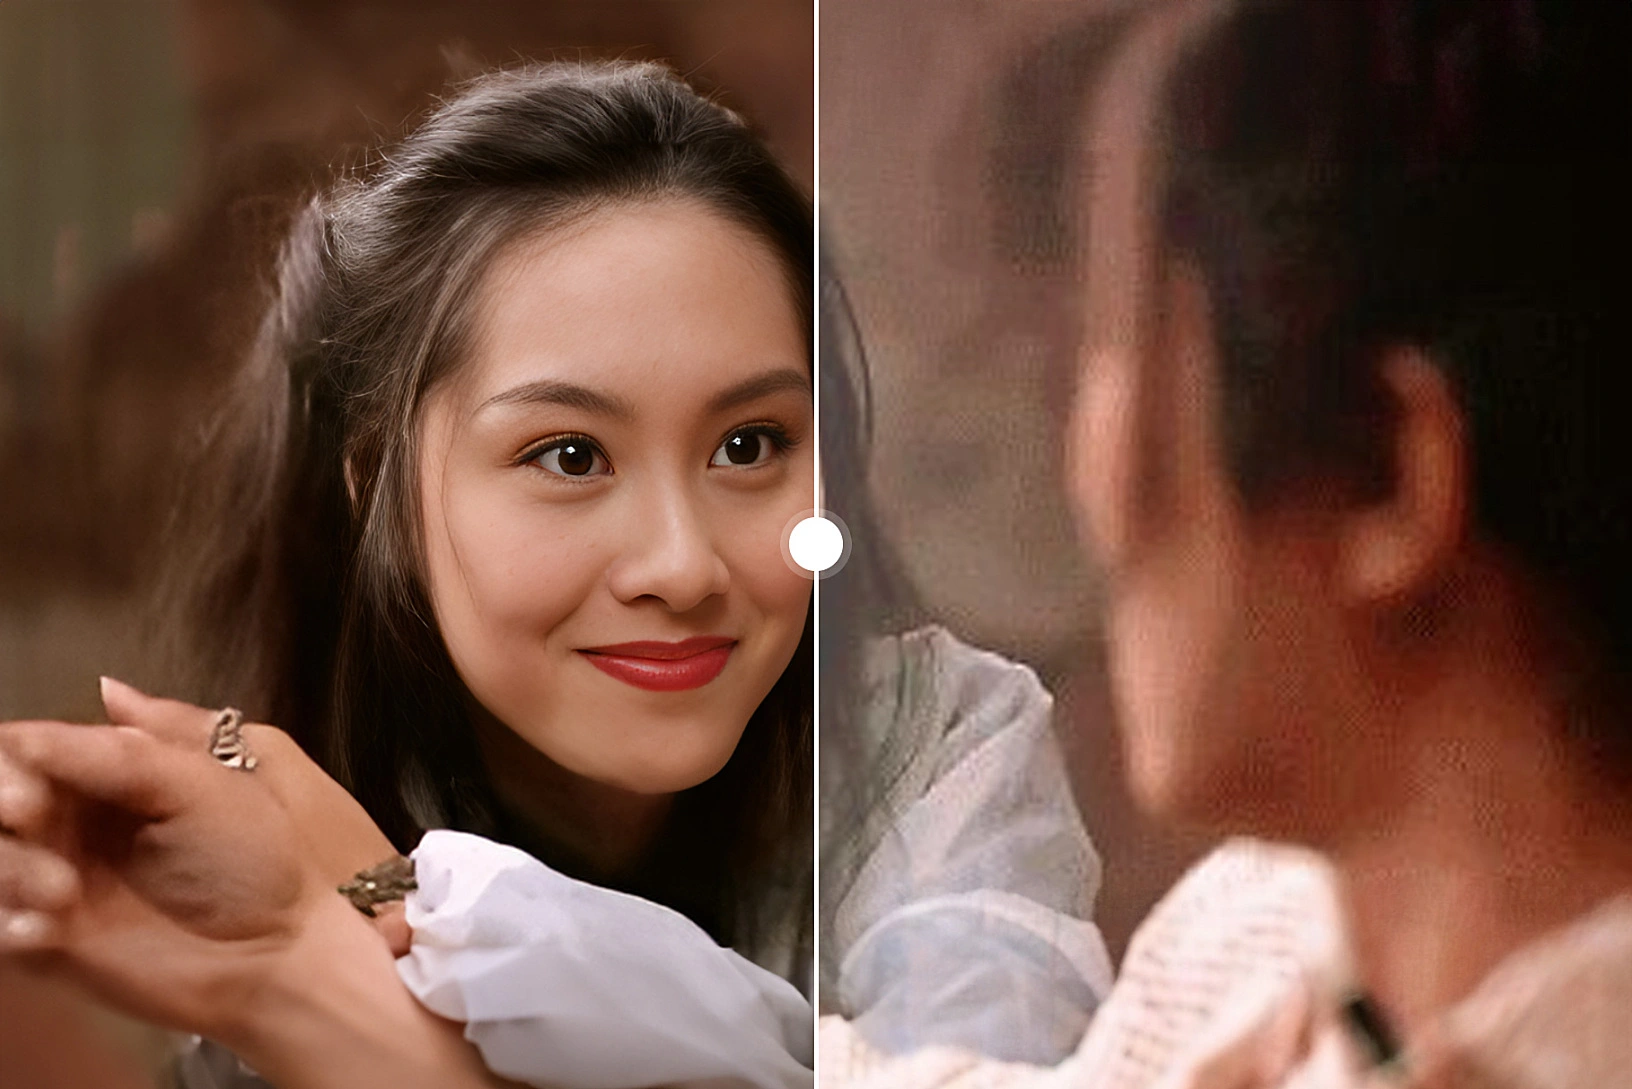 image-to-image
fal-ai/codeformerFix distorted or blurred photos of people with CodeFormer.