 image-to-image
FLUX.2 [klein] 4B Base
fal-ai/flux-2/klein/4b/base/editImage-to-image editing with FLUX.2 [klein] 4B Base from Black Forest Labs. Precise modifications using natural language descriptions and hex color control.
Browse the public fal model directory. Models become callable through Kaista Cloud only after supply, pricing, and compatibility review.
image-to-imagefal-ai/flux-2/klein/4b/base/editImage-to-image editing with FLUX.2 [klein] 4B Base from Black Forest Labs. Precise modifications using natural language descriptions and hex color control.
 image-to-image
fal-ai/marigold-v2Estimate depth from a single image with Marigold V2, a diffusion-based depth model built on Qwen-Image-Edit, returning a colorized depth map.
 image-to-image
luma/agent/uni-1/v1/editLuma Uni-1 Edit reworks a source image from a text instruction, preserving the original composition while applying style changes and following optional reference images to steer the result.
 image-to-image
fal-ai/hy-wu-editImage editing with HY-WU. Transfer outfits, swap faces, and blend textures instantly—no finetuning needed, just describe what you want and provide reference images.
 image-to-image
google/virtual-try-onGenerate realistic virtual try-on images from a person image and a clothing product image.
 image-to-image
ideogram/v4/image-to-imageIdeogram V4.0q Image-to-Image transforms an input image with a text prompt, restyling and reworking the composition while preserving its core structure for prompt-faithful, high-fidelity edits.
 image-to-image
luma/agent/uni-1/v1/max/editLuma Uni-1 Max Edit applies text-guided edits to a source image at maximum fidelity, holding the original structure while honoring reference images for precise, high-detail revisions.
 image-to-image
fal-ai/image-editing/object-removalRemove unwanted objects or people from your photos while seamlessly blending the background.
 image-to-image
fal-ai/ideogram/v3/layerize-textIdeogram Layerize takes an existing flat graphic, removes text, and returns structured text containers you can edit/recompose in html or json format.
image-to-imagefal-ai/image-editing/reframeThe reframe endpoint intelligently adjusts an image's aspect ratio while preserving the main subject's position, composition, pose, and perspective
 image-to-image
fal-ai/flux-2/klein/realtimeRealtime generation with FLUX.2 [klein] from Black Forest Labs.
 image-to-image
 image-to-image
fal-ai/hunyuan_worldHunyuan World 1.0 turns a single image into a panorama or a 3D world. It creates realistic scenes from the image, allowing you to explore and view it from different angles.
 image-to-image
fal-ai/ideogram/v3/remixReimagine existing images with Ideogram V3's remix feature. Create variations and adaptations while preserving core elements and adding new creative directions through prompt guidance.
 image-to-image
fal-ai/live-portrait/imageTransfer expression from a video to a portrait.
 image-to-image
fal-ai/z-image/turbo/image-to-image/loraGenerate images from text and images using custom LoRA and Z-Image Turbo, Tongyi-MAI's super-fast 6B model.
image-to-imagefal-ai/image-editing/text-removalRemove all text and writing from images while preserving the background and natural appearance.
 image-to-image
microsoft/mai-image-2.5-pro/editApply precise, controllable edits to a reference image while preserving composition, typography, identity, and fine visual detail.
 image-to-image
fal-ai/recraft/upscale/creativeEnhances a given raster image using the 'creative upscale' tool, increasing image resolution, making the image sharper and cleaner.
 image-to-image
fal-ai/fast-sdxl/image-to-imageRun SDXL at the speed of light
 image-to-image
fal-ai/flux-pro/v1/vtoGenerate virtual try-on results from a person image plus one or more garment references.
 image-to-image
fal-ai/ideogram/character/editModify consistent characters while preserving their core identity. Edit poses, expressions, or clothing without losing recognizable character features
 image-to-image
fal-ai/flux-kontext-lora/inpaintFast inpainting endpoint for the FLUX.1 Kontext [dev] model with LoRA support, enabling rapid and high-quality image inpainting with reference images, while using pre-trained LoRA adaptations for specific styles, brand identities, and product-specific outputs.
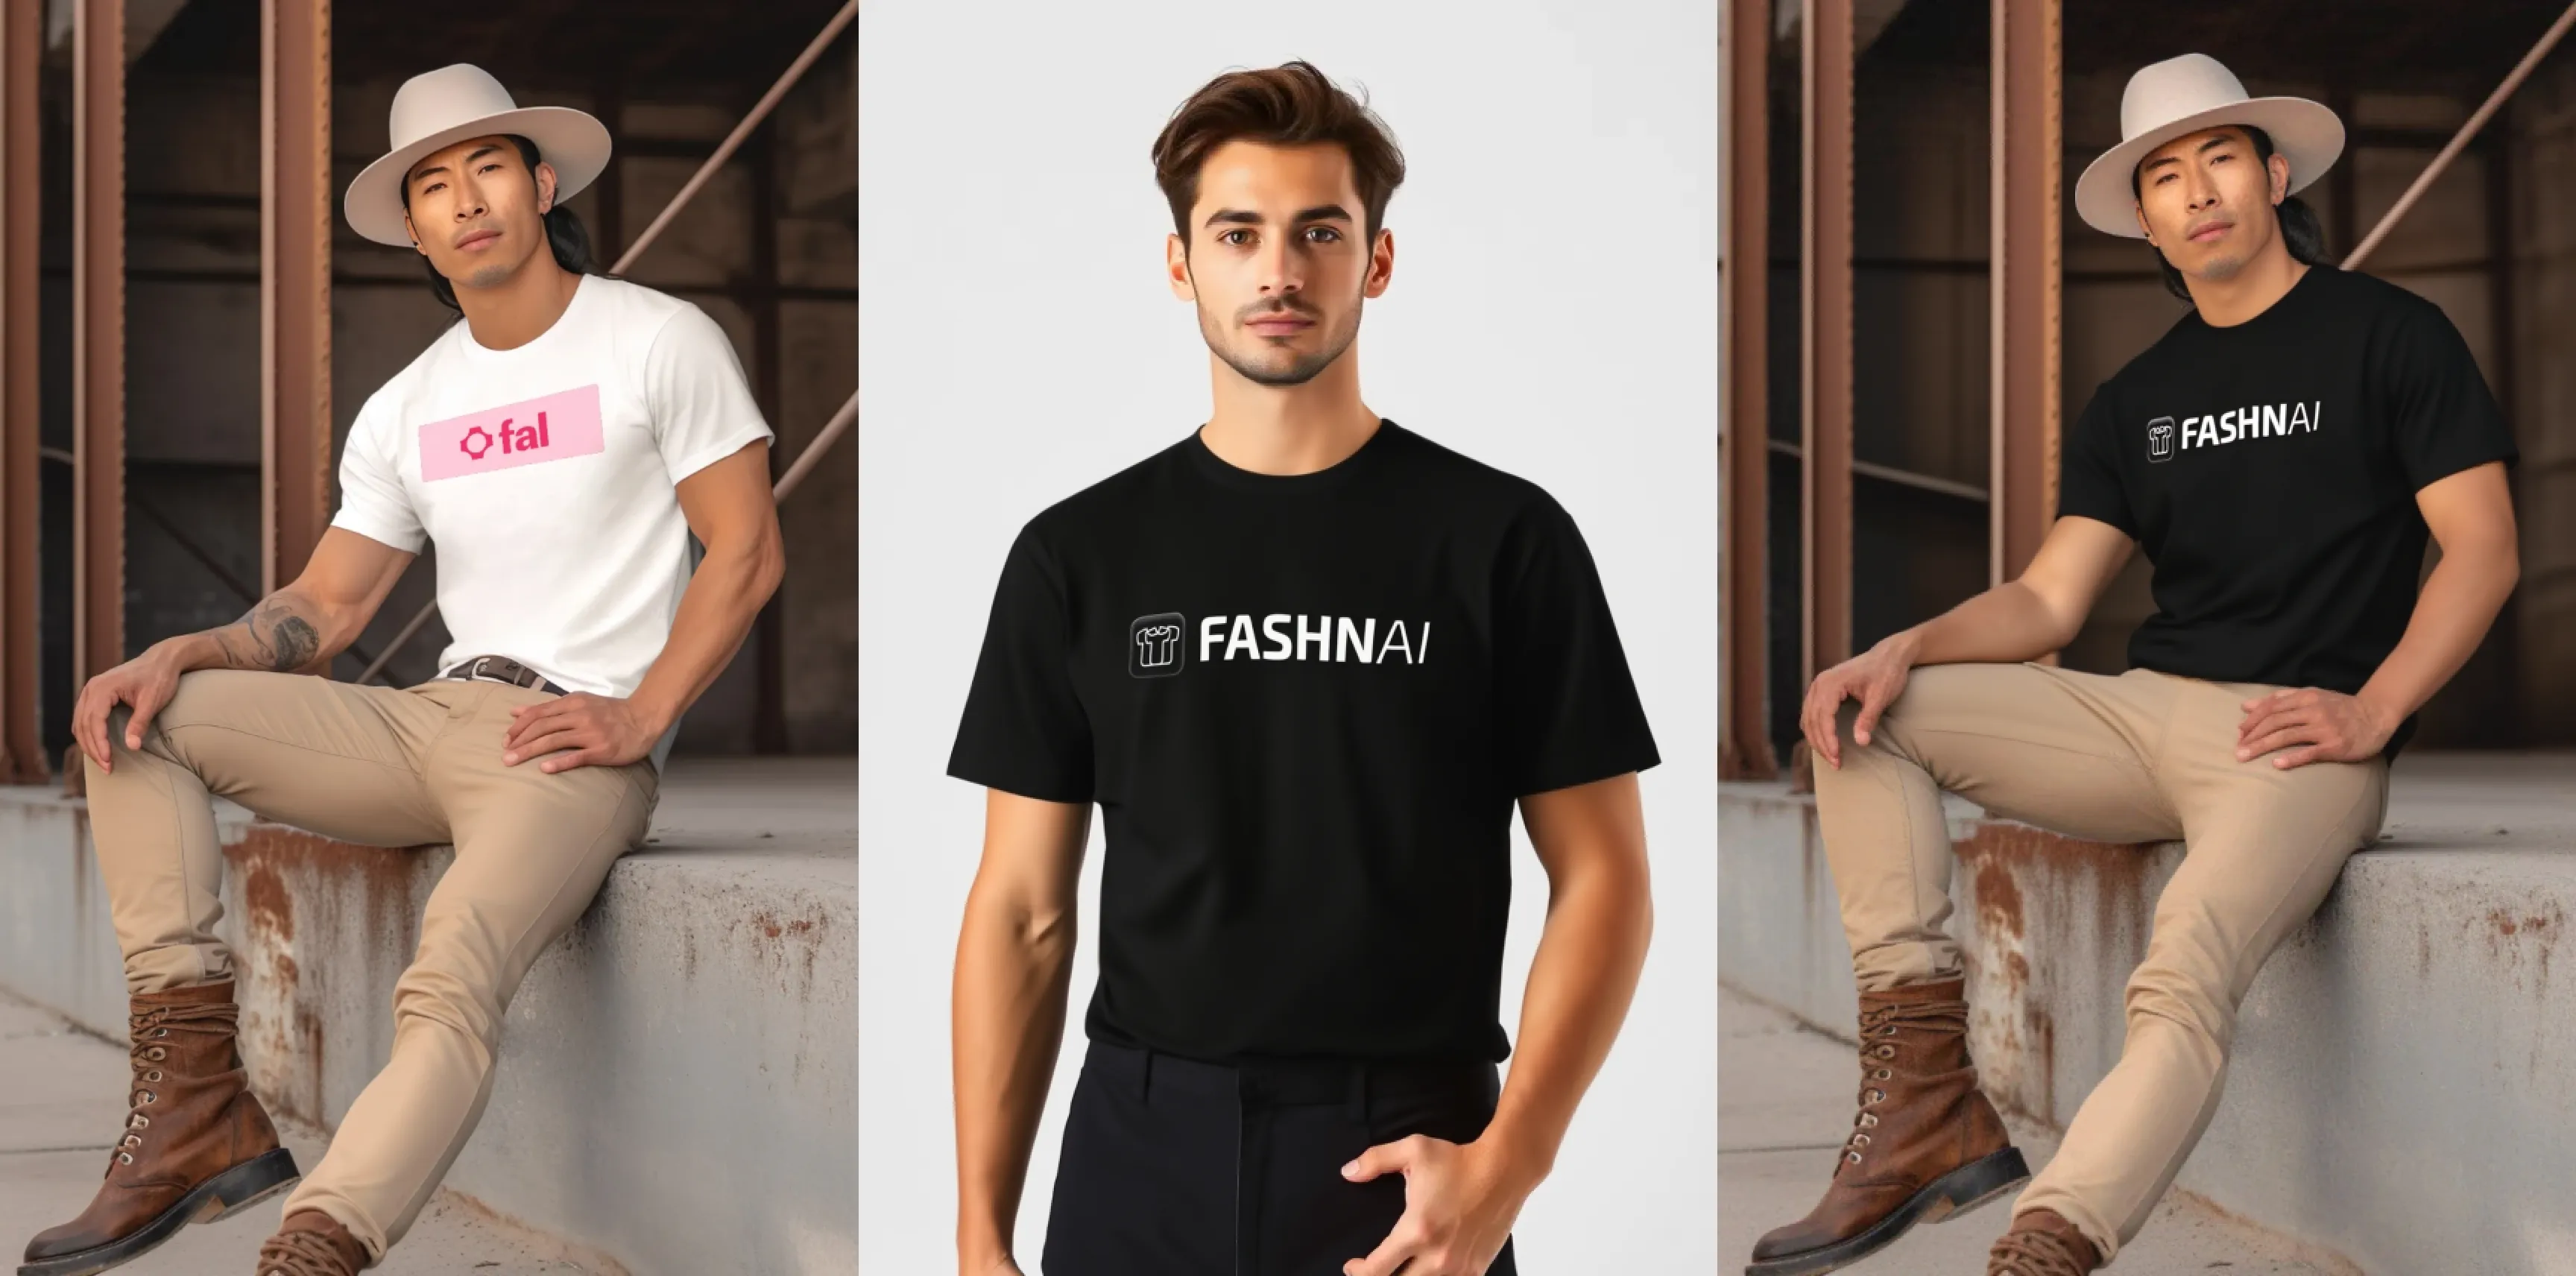 image-to-image
fal-ai/fashn/tryon/v1.5FASHN v1.5 delivers precise virtual try-on capabilities, accurately rendering garment details like text and patterns at 576x864 resolution from both on-model and flat-lay photo references.
 image-to-image
fal-ai/image-apps-v2/photo-restorationRestore old or damaged photos by fixing colors, scratches, and resolution.
 image-to-image
fal-ai/minimax/image-01/subject-referenceGenerate images from text and a reference image using MiniMax Image-01 for consistent character appearance.
 image-to-image
fal-ai/bria/genfillBria GenFill enables high-quality object addition or visual transformation. Trained exclusively on licensed data for safe and risk-free commercial use. Access the model's source code and weights: https://bria.ai/contact-us
 image-to-image