 image-to-image
Florence-2 Large
fal-ai/florence-2-large/ocr-with-regionFlorence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks
Browse the public fal model directory. Models become callable through Kaista Cloud only after supply, pricing, and compatibility review.
image-to-imagefal-ai/florence-2-large/ocr-with-regionFlorence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks
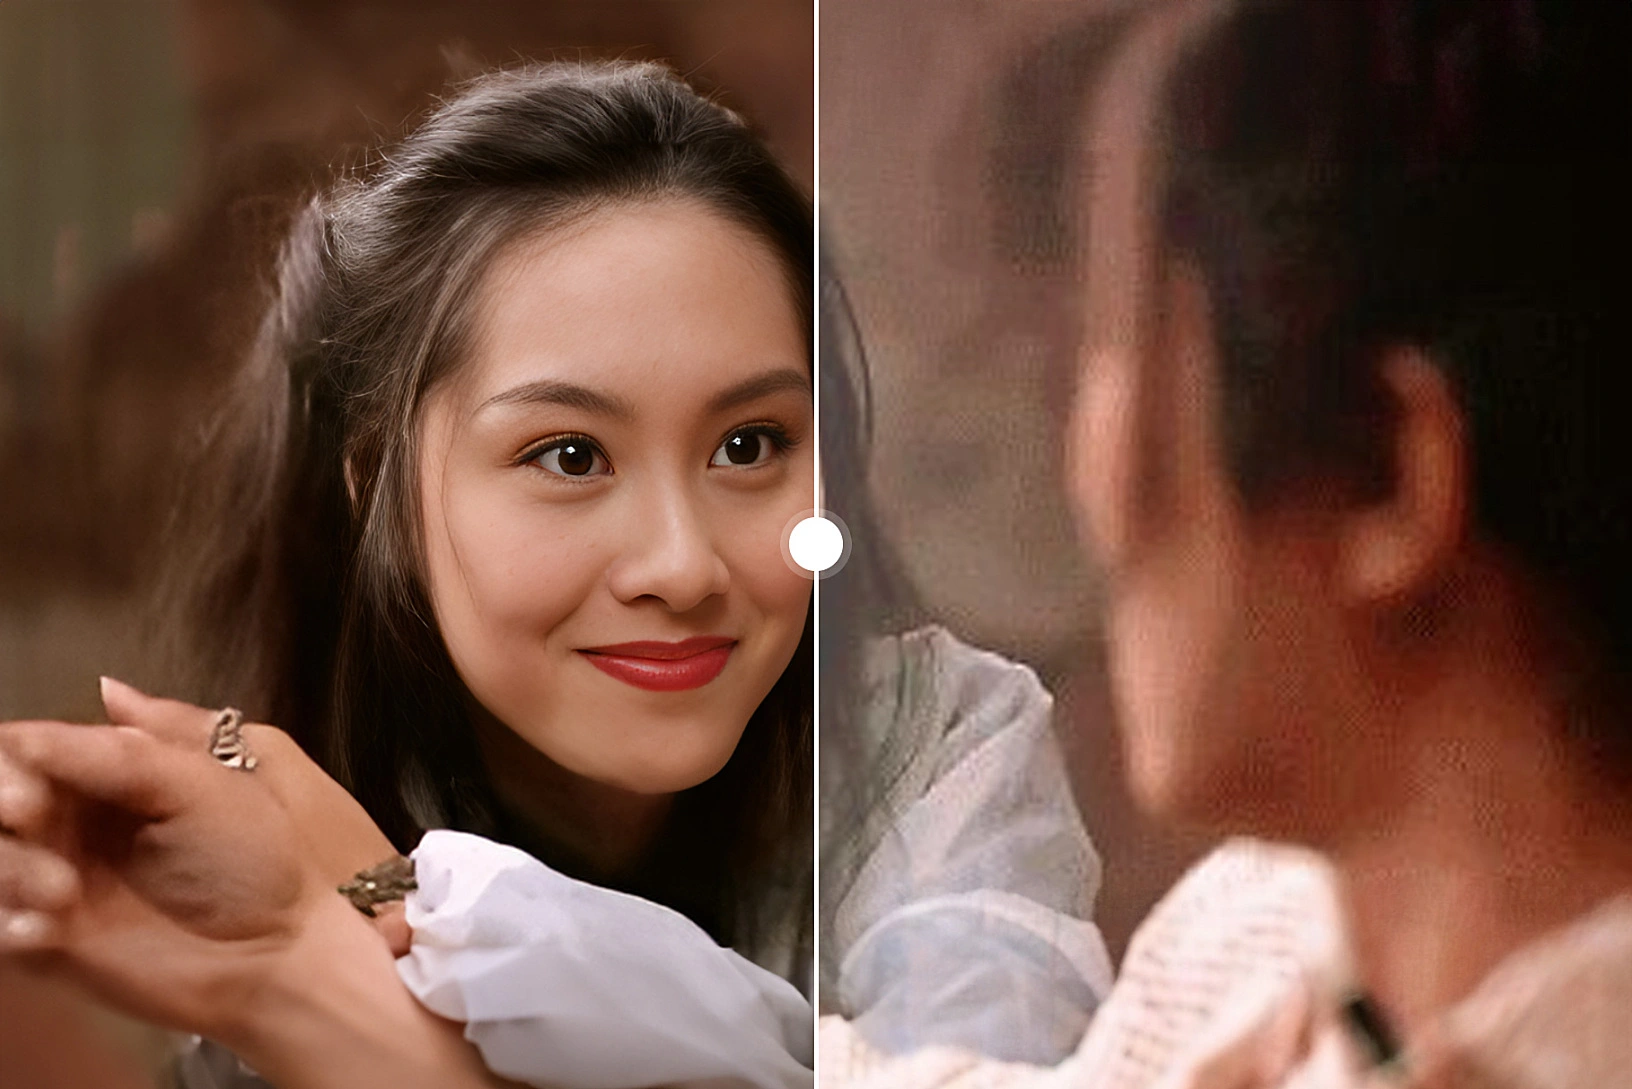 image-to-image
fal-ai/codeformerFix distorted or blurred photos of people with CodeFormer.
 image-to-image
fal-ai/flux-2-flex/editImage editing with FLUX.2 [flex] from Black Forest Labs. Supports multi-reference editing with customizable inference steps and enhanced text rendering.
 image-to-image
fal-ai/flux-2/lora/editImage-to-image editing with LoRA support for FLUX.2 [dev] from Black Forest Labs. Specialized style transfer and domain-specific modifications.
 image-to-image
blackforestlabs/flux-3/klein/edit-image/loraEdit images fast with distilled FLUX 3 Image Klein and up to 3 custom LoRAs.
 image-to-image
bria/guided-remove-backgroundBackground removal you steer with a prompt. Starts from the same clean cut as Bria RMBG, then adds, drops or isolates objects from plain words like "the person with the mat and the plant" or "only the chair". Original pixels, real alpha, nothing repainted.
 image-to-image
fal-ai/wan/v2.7/pro/editEdit and transform images using text instructions with the WAN 2.7 Pro model for precise, professional-grade image modifications.
 image-to-image
fal-ai/seedvr/upscale/image/seamlessUse SeedVR2 to upscale images, retaining seamless tiling
 image-to-image
fal-ai/workflow-utilities/extract-nth-frameFFMPEG Untility for Extracting nth Frame
 image-to-image
fal-ai/qwen-image-edit-2511/loraEndpoint for Qwen's Image Editing 2511 model with LoRa support.
 image-to-image
fal-ai/patinaPATINA creates seamless high-resolution normal, roughness, basecolor (albedo), height (displacement) and metalness maps from images
 image-to-image
fal-ai/sam-3/image-rleSAM 3 is a unified foundation model for promptable segmentation in images and videos. It can detect, segment, and track objects using text or visual prompts such as points, boxes, and masks.
 image-to-image
microsoft/mai-image-2.5/editMAI-Image-2.5 is Microsoft's photorealistic image generation and editing model that turns text prompts or uploaded images into high-quality, design-ready visuals with fine-grained, pixel-level control.
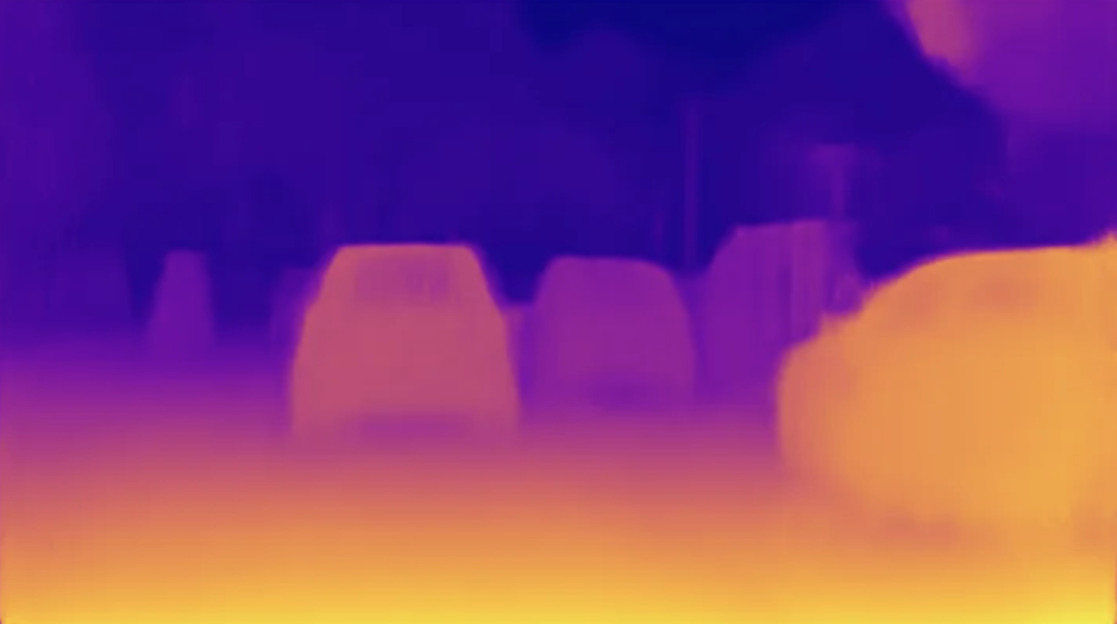 image-to-image
fal-ai/imageutils/depthCreate depth maps using Midas depth estimation.
 image-to-image
fal-ai/finegrain-eraser/maskFinegrain Eraser removes any object selected with a mask—along with its shadows, reflections, and lighting artifacts—seamlessly reconstructing the scene with contextually accurate content.
 image-to-image
fal-ai/object-removal/maskRemoves mask-selected objects and their visual effects, seamlessly reconstructing the scene with contextually appropriate content.
 image-to-image
fal-ai/bria/product-shotPlace any product in any scenery with just a prompt or reference image while maintaining high integrity of the product. Trained exclusively on licensed data for safe and risk-free commercial use and optimized for eCommerce.
 image-to-image
fal-ai/qwen-image-edit/inpaintInpainting Endpoint for the Qwen Edit Image editing model.
 image-to-image
topaz/upscale/image/transparentProfessional transparent-image upscaling powered by Topaz Labs. Preserves the alpha channel end to end with PNG output. Best for logos, stickers and assets with transparency.
 image-to-image
fal-ai/bria/background/replaceBria Background Replace allows for efficient swapping of backgrounds in images via text prompts or reference image, delivering realistic and polished results. Trained exclusively on licensed data for safe and risk-free commercial use
 image-to-image
fal-ai/kling-image/v3/image-to-imageKling Image V3: Latest kling image model
 image-to-image
fal-ai/feynobgFeyNobg is a state of the art AI model for background removal from feyninc
 image-to-image
fal-ai/flux-2/klein/9b/base/edit/loraImage-to-image editing with LoRA support for FLUX.2 [klein] 9B Base from Black Forest Labs. Specialized style transfer and domain-specific modifications.
 image-to-image
fal-ai/hunyuan-image/v3/instruct/editImage editing endpoint for Hunyuan Image 3.0 Instruct.
 image-to-image
fal-ai/image-editing/photo-restorationRestore and enhance old or damaged photos by removing imperfections, adding color while preserving the original character and details of the image.
image-to-imagefal-ai/florence-2-large/object-detectionFlorence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks
 image-to-image
fal-ai/sam2/auto-segmentSAM 2 is a model for segmenting images automatically. It can return individual masks or a single mask for the entire image.
image-to-imagefal-ai/florence-2-large/open-vocabulary-detectionFlorence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks